Start with a task whose result you can observe
Choose a concrete task and define what makes its response usable before collecting examples. Specify the recipient, purpose, required data and the assistant's boundaries. A clear objective helps you select cases that teach a specific decision, instead of collecting texts that simply sound polished without showing whether they accomplish the intended work.
I want AI to work with my way of thinking, the business criteria and the context I provide. That requires me to make those criteria understandable. A folder full of unexplained outputs leaves an essential part of the assessment inside my head, inaccessible to anyone trying to reuse it.
Imagine a fictional company using an assistant to answer demonstration requests. Its objective might be to clarify the next step and collect one missing detail. A long response about the company's history can be accurate and still be unsuitable for that particular request from a prospective customer.
Keep the original request alongside the response. Without it, someone consulting the example might mistake a decision specific to that case for a general rule. Record what information was available at the time too, because a good response depends on what could reasonably be known and done.
This preparation is part of giving AI context without collecting information indiscriminately. Each example should justify the space it occupies. If it teaches no relevant choice, boundary or exception, it can probably stay in the working archive instead of entering the main instructions.
To prepare your next step, explore AI assistants for internal knowledge.
Separate factual errors, task deviations and preferences
Classify the reason for your assessment so the assistant understands what needs changing. An invented price is a factual error; answering a different question is a task deviation; preferring shorter sentences is a style choice. These categories require different corrections and should not all receive an identical rejection label without any further explanation.
In the demonstration example, inventing an available date invalidates the commitment being presented. A response with the correct date but no explanation of how to confirm the booking may be incomplete. An excessively formal opening may simply need editing, while retaining all the factual information that was already correct.
Avoid writing only “I did not like it”. Add the reason and desired outcome: “The opening takes too long to address the request; start by confirming the next step.” That instruction allows correction without removing important information or making the assistant guess which personal preference prompted the rejection.
It also helps to recognise what was right in a rejected response. You can preserve a clear summary while correcting an inappropriate promise. If everything is labelled bad, the next output might abandon exactly the part you wanted to retain, creating additional review work with no useful purpose.
A preference needs a scope. Liking an informal tone in an advertisement does not mean wanting the same tone in a complaint response. Record the channel, audience and situation where the preference applies, so the library teaches adaptation instead of making every conversation sound identical.
Build pairs that make the difference apparent
Place an unsuitable response beside a corrected version and explain the decisive change. Whenever possible, keep the request and context unchanged between the two. The contrast then shows which criterion changed, without confusing the effect of a correction with differences in audience, available information or commercial objective between the examples under review.
In a hypothetical case, the unsuitable version confirms a feature absent from the documentation. The corrected version explains what is documented and requests validation of the remaining point. The lesson is to preserve the boundary between confirmed information and an assumption, rather than memorise one particular sentence.
In another pair, both versions may be factually accurate. The difference is that one presents three incompatible next steps while the other selects the step appropriate to the request. The criterion here is clear direction. Write it beside the example so the choice does not look like an arbitrary preference.
If you work on advertising variations with AI, contrast two texts that merely change words with two that explore different motivations. The explanation should identify the change in argument. Replacing adjectives without changing the hypothesis does not teach the assistant what you consider a useful variation.
You do not need to rewrite everything in each pair. Isolating the passage that caused the problem makes the decision easier to see, provided the necessary context remains accessible. Keep the complete response in its original record and bring only what is needed to understand and apply the criterion into the library.
Keep the library small, identifiable and current
Organise examples by task and give each an identifier, a date and a note explaining the decision. Distinguish permanent rules from local preferences and exceptions. Review duplicate or incompatible cases whenever the process changes, so the assistant does not receive old and new guidance presented as if both had exactly the same authority today.
An initial library might cover an accepted response, a factual error, a tone problem and a situation with missing information. There is no magic quantity. The collection should represent differences that matter to the work, without repeating the same pattern dozens of times using slightly different words.
Preserve the change history without loading all of it into every task. If a commercial condition changes, an old example may remain useful for understanding a past decision. It must, however, be marked as historical and excluded from the references applicable to current proposals and commitments.
Use fictional examples or materials you are allowed to reuse in that context. If a real case contains client information, retain only the elements necessary to teach the criterion and respect established access boundaries. A learning library should not expose restricted information to people who do not need it.
Define who can validate a rule. The assistant may suggest that several corrections indicate the same preference, but that interpretation needs confirmation when it changes the working method. A passing compliment about one piece should not automatically become a requirement for every item produced in future.
Check whether examples improve responses to new requests
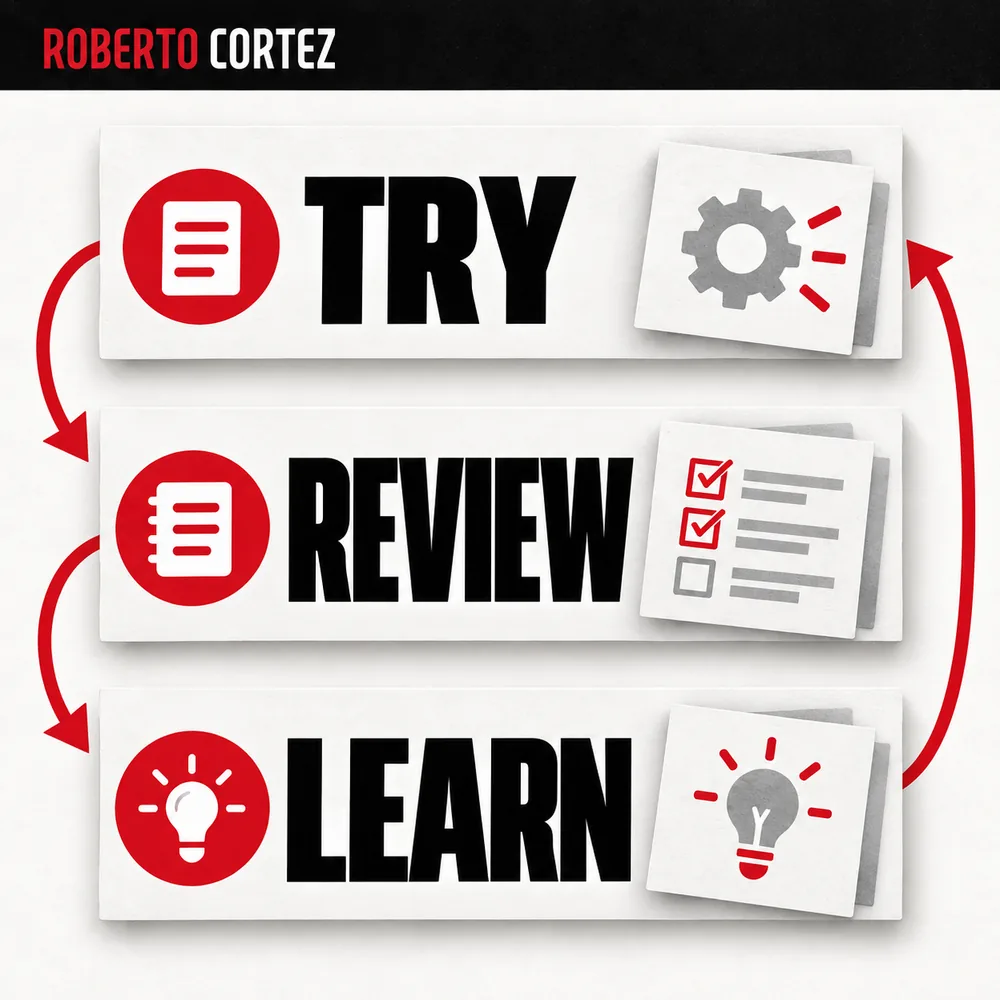
Test the library on requests that were not used to construct its examples, then compare the outputs against criteria defined beforehand. Check facts, suitability and usefulness alongside style. The aim is to discover whether the assistant applies the decision to new situations, rather than merely repeating the wording of an example it has just received.
Reserve some cases for this evaluation. They can include a complete question, missing information and a request with unusual conditions. Record which examples were supplied and which instruction version was used, so you can relate an improvement or failure to the particular change that preceded it.
Choosing a model for the business task still matters, but switching models does not replace clear assessment. If the criterion remains implicit, you may receive different answers without knowing which is closer to what you need. Make the assessment observable first, then compare alternatives under similar conditions.
When a new example fixes a failure, test cases that previously worked again. An instruction to be briefer may remove a necessary condition. An instruction to seek clarification may generate questions about data already present. Improvement requires observing these consequences for other responses as well as the targeted correction.
Keep the reason for the correction alongside the final version. That reasoning makes the work reusable when the task changes or another person reviews the assistant. The library should support better decisions, fewer repeated uncertainties and boundaries the team can explain, rather than merely store outputs that somebody once approved.