A small team has little spare capacity to supervise several experiments at once. If the same person answers customers, prepares proposals and coordinates delivery, an overly broad pilot can become another obligation with no room in the calendar. The initial choice needs to respect that capacity and the team's existing commitments.
I like to start by observing the work and defining the result that should improve. The tool follows that choice. With a specific task, it becomes possible to understand whether AI contributes to the operation and which parts still depend on the team's knowledge, judgement and ability to correct mistakes.
Choose a task with an impact you can observe
Choose a task with an identifiable use and a current execution that can be observed. Weigh expected impact against preparation and supervision effort. For a first pilot, look for an improvement significant enough to justify testing and limited enough for you to understand what happened during the experiment carried out by the team.
An inventory before choosing an automation may produce several options. At this stage, the decision is to select one. A long list helps only if you can compare frequency, difficulty, information availability and the consequences of mistakes across the candidate tasks.
Imagine three hypothetical options: preparing an internal meeting summary, automatically answering every commercial enquiry or reorganising the entire operation. The first offers an output that can be reviewed directly; the second involves consequences for customers; the third combines too many decisions for a limited initial experiment.
This does not mean every team should start with summaries. The selected task needs to be useful in your context. If nobody reads summaries, a perfect pilot in that activity offers little value; if meetings produce decisions that regularly disappear, the same option may deserve attention.
Write the need as a verifiable statement, such as preparing a list of decisions and tasks from a meeting. Avoid objectives as broad as making the team more productive, because they make comparison between the expected result and the pilot's actual output unnecessarily difficult.
To prepare your next step, explore Assessing business readiness for AI.
Confirm that data and a capable reviewer are available
A pilot needs available information and someone who can distinguish a correct result from a merely convincing one. Confirm both before starting development. If the team cannot assess the response, it will struggle to learn from the test and decide whether continuing is justified by the results and the effort involved.
For the meeting example, you need an authorised and sufficiently complete source. The reviewer should know which decisions were made and recognise when a suggestion has been mistaken for a commitment. Without that reference, a well-written list may look useful while assigning responsibilities that nobody actually accepted.
Choose representative examples from normal work. Include a straightforward case and another in which the information is less organised. The test should show how the system responds to the variation the team encounters rather than depending entirely on the easiest example available to prepare for the demonstration.
Check what may be used in the experiment too. Customer data, internal messages and third-party documents require attention to access and context. Clearly identified fictional data can help test the initial structure before real, authorised information is introduced into the working process and assessed by the responsible person.
Data availability also means being able to find and understand it. If the project begins with several weeks of reconstructing scattered archives, that preparation is part of the scope. Recognise it early and decide whether a different pilot could produce useful learning with fewer dependencies.
Define the output, the owner and the experiment's boundary
Before running the pilot, define what it will produce, who reviews it, which actions are authorised and when the experiment ends. Include the cases that remain outside its scope. These decisions reduce differing interpretations within the team and let you supervise the trial without turning every new situation into an improvised decision.
A short brief can answer the essential questions: what is the input, what is the output, who validates it, what counts as an error and what happens when information is missing? The owner needs time to observe the trial and authority to stop an execution that no longer meets the agreed conditions.
For meeting summaries, the pilot can prepare a draft for review and end with that delivery. Publishing tasks into another system, assigning deadlines or messaging participants would be additional actions. Those options can be explored later, once the team understands whether the draft itself is reliable enough to use.
The cost of repeated decisions within a business is a reminder that reviewing also takes time. Reserve that effort within the experiment. Without it, the pilot can accumulate outputs that nobody has the capacity to evaluate in a useful and consistent way.
Choose a review date that suits the task's frequency. A daily activity offers several cases within a week; a monthly activity may require a different period or authorised historical examples. The timetable should allow evidence to accumulate without leaving the trial open indefinitely and dependent on somebody remembering it.
Compare quality, effort and ease of correction
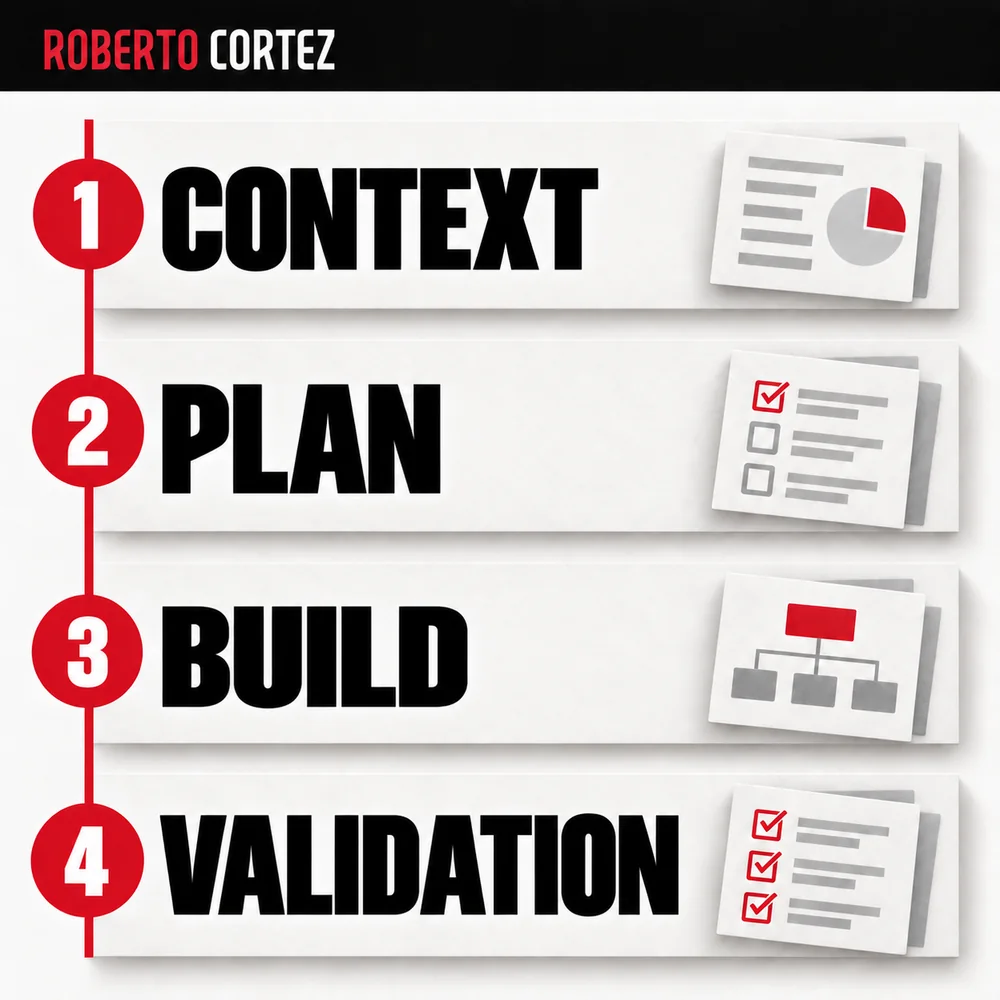
Evaluate the pilot through output quality, total usage effort and the ease of correcting discovered mistakes. Record preparation and review time as well as execution. A fast response represents an improvement only when it can be used and when the additional work fits within the team's actual capacity to handle it.
For the chosen example, check whether all decisions were preserved, task owners were identified correctly and unresolved questions were marked as such. These criteria are more useful than simply asking whether the text looks good. The assessment stays connected to the function the summary is meant to perform.
Record corrections briefly and distinguish content errors from presentation preferences. A long sentence may be easy to shorten; a responsibility assigned to the wrong person requires a correction in meaning. The team needs to understand which mistakes restrict use and which can be handled through a simple editing step.
Observe the correction process itself. If the reviewer can amend the draft and proceed, there is a straightforward recovery path. If they must return to the source and redo the entire task, the advantage may disappear even when most individual sentences are well written and appear plausible.
Keep comparison with the previous process proportional to the experiment. A few cases can reveal problems and inform the next test, but they do not justify turning an early impression into a dependable forecast for the whole business. Record what you observed and what still needs to be tried.
Close the pilot with a decision and a specific next scope
At the end of the agreed period, decide whether the task continues unchanged, needs adjustments, can gain autonomy or should stop. Base that decision on observed cases and required corrections. Define a specific next scope so the learning produces an understandable change in how the team works and supervises the activity.
If the summary is useful but owners are still confused, keep automatic preparation and make that check mandatory. If the difficulty comes from poor source information, improving collection may be the next step. These conclusions lead to different actions and should not be combined into a vague instruction to improve the AI.
An experiment that ends can still leave useful learning. The task may be infrequent, the output unused or the exceptions too demanding to supervise. Recording the conclusion helps select the next option and prevents the team from repeating an attempt under the same conditions without addressing the underlying problem.
When organising the first month of a project, make room for these decisions between phases. The pilot should help select subsequent work, including which ideas no longer make sense to pursue at that point in the business.
A small team gains clarity when it can explain the experiment in a sentence, show a few results and justify the decision it reached. That provides a useful basis for expanding AI use: understanding the task, knowing how to assess the output and taking responsibility for what happens next.